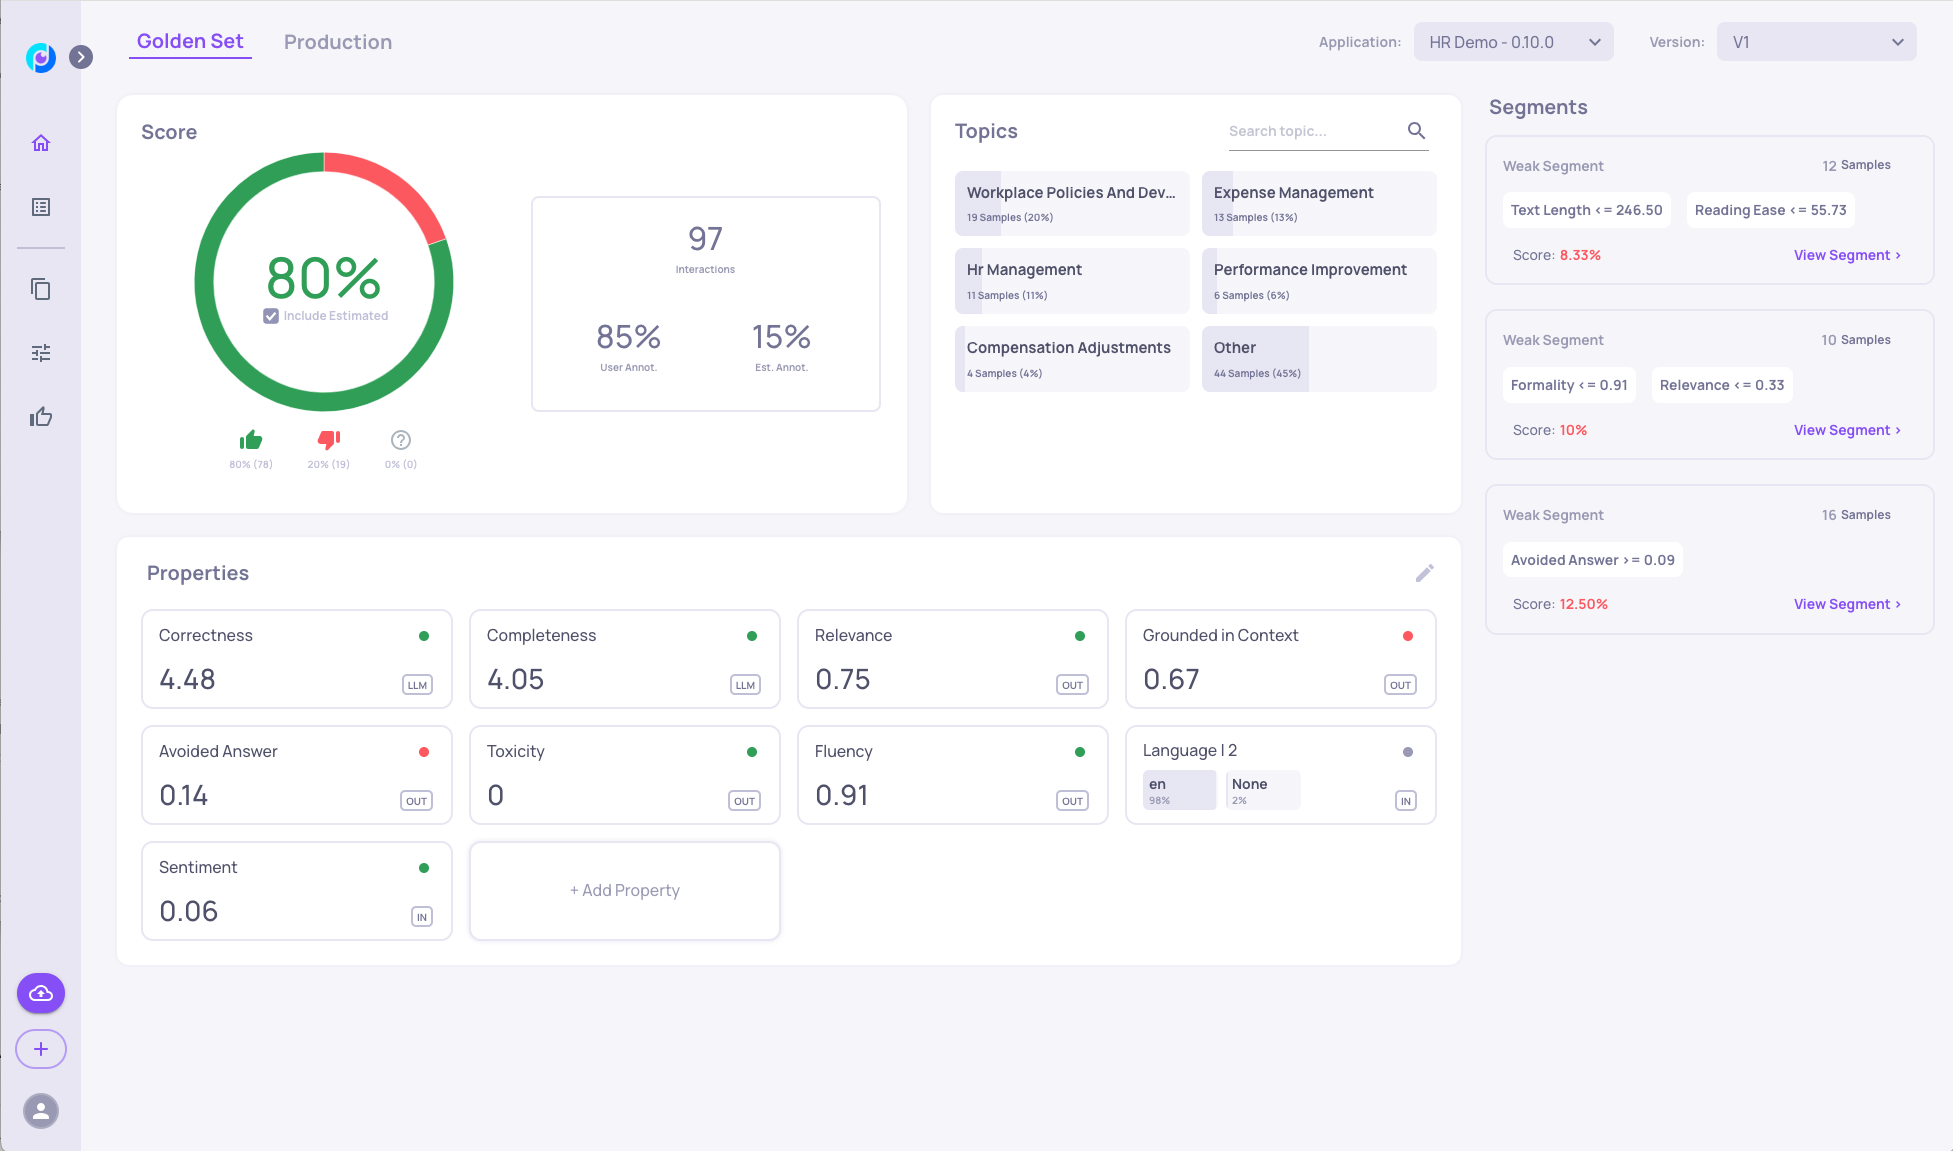
Test, Evaluate,
& Monitor LLM apps
support all parts of your workflow.
- Mitigates Hallucinations
- Full lifecycle Support
- Automated Evaluation
Evaluation Components

Version Comparison

Properties

Golden Set Management

Monitoring


Automated Annotation
with Manual Override
Get both manual and automated annotations to
evaluate all the interactions with the LLM.
Create a ground truth with manual annotations
and fine-tune your automatic annotation pipeline
to provide more accurate results.

Compare Experiments and
Pre-Production Versions
Experiment with different:
- LLMs
- Vector databases
- Knowledge sources
- Embedding models
- Retrieval methods
Make product decisions and vendor selection
metric-driven.
Understand How Each Step
Can Be Improved
Rigorously check each aspect of your LLM-
powered application using Deepchecks’s
custom and off-the-shelf properties
- Quality Metrics
- Safety Metrics
- LLM Metrics
- Quantitative Metrics
- User-defined metrics

Build, Expand & Explore
Your Golden Set
“Golden Set” is like the “test set” from classic ML,
adapted to benchmark generative applications.
- Explore your annotated responses to learn
what is & isn’t working - Generate or expand your Golden Set with
Deepchecks LLM Evaluation
LLM Apps Production
Monitoring
LLM applications require much more than just
input and output format validation.
Hallucinations, harmful content, model
performance degradation, or a broken data
pipeline are common problems that may arise
over time.
Debugging and Root-
Cause Analysis
Understand methodically where your problems
lie within your LLM application.
- Automatically identifies your weakest
segments - Manually segment your data to identify more
weak segments - See all the detailed steps of our LLM app to
find the one that failed
 LLMOps.Space
practitioners. The community focuses on LLMOps-related content, discussions, and
events. Join thousands of practitioners on our Discord.
 Join Discord Server
Past Events

 Philip Tannor
 Yaron Friedman


Featured Content


 Amos Rimon
